
Yes, you can put ChatGPT on your website, and three practical routes get you there: a hosted wrapper, an OpenAI ChatKit embed, or a raw OpenAI API build. Most teams should start with a hosted wrapper or ChatKit for a fast, controlled launch. Build a raw API integration only when you need custom retrieval, streaming, or compliance controls. Whichever path you pick, a server-side proxy and grounded content are non-negotiable.
TL;DR:
- Most teams should start with a hosted wrapper or ChatKit for rapid deployment, reserving raw API builds for highly customized or compliance-heavy scenarios.
- OpenAI ChatKit offers an official, modular SDK that balances control and ease of setup, with options for hosted or self-hosted deployment based on data residency needs.
- Building directly on the OpenAI API provides full control over retrieval, streaming, and compliance but requires significant engineering effort and ongoing monitoring.
- Successful implementation depends on content triage, secure token management, grounding citations, and placement in high-engagement areas like pricing or contact pages.
- Post-launch, continuous content management, prompt tuning, and analytics tracking are essential to maintain accuracy, trust, and conversion.
Table of Contents
- Comparing the Main Ways to Add ChatGPT to Your Site
- How Does OpenAI ChatKit Work for Website Embeds?
- What Does a Raw OpenAI API Integration Require?
- Are Hosted Chatbot Wrappers Worth It for Most Businesses?
- Best Practices for Grounding, Privacy, and Cost Control
- How Do You Roll Out a ChatGPT Website Assistant?
- What an Agency Adds to a ChatGPT Website Rollout
- Build vs. Buy: A Practical Recommendation
- Getting Help With Implementation and AI Visibility
- Authoritative Docs and Guides
- Sources
- FAQ
Comparing the Main Ways to Add ChatGPT to Your Site
The decision usually comes down to how much control your team wants versus how fast you need to ship. Putting ChatGPT on a website is not one thing. It is a spectrum ranging from "install a script tag" to "build and maintain your own AI product."
At one end sits the hosted wrapper: a third-party service that crawls your site, indexes your content, and gives you an embeddable chat widget with minimal setup. At the other end sits a raw OpenAI API integration, where your engineering team owns the retrieval pipeline, the streaming logic, and every prompt that goes out the door. In between sits OpenAI ChatKit, the official embeddable SDK that gives you more structure than a wrapper but far less overhead than building from scratch.
Here is how the three stack up on the factors that actually matter:
- Hosted wrapper — fastest to launch, lowest engineering lift, but you depend on someone else's grounding quality and data handling.
- OpenAI ChatKit — official SDK with hosted or self-hosted options, moderate setup, strong middle ground for teams that want control without building everything.
- Raw OpenAI API (DIY) — full control over retrieval, latency, and compliance, but the highest build and maintenance cost.
Two other approaches come up often and deserve a quick mention. Custom GPTs, built inside ChatGPT itself, work well for internal prototyping or gated use inside your own workspace, but they are not built for public-facing website embedding. Browser extensions like WebChatGPT let an individual user's ChatGPT session pull in live web results, but that is a personal browsing tool, not something you install for your site's visitors.
Marketing teams with no engineering resources tend to land on wrappers. Product teams building a differentiated support or sales experience tend to land on ChatKit or the raw API. Compliance-heavy organizations, think finance or healthcare, almost always end up on the raw API path because they need to control exactly what data leaves their servers.
How Does OpenAI ChatKit Work for Website Embeds?
ChatKit is OpenAI's official embeddable chat SDK, and it splits the difference between a plug-and-play wrapper and a from-scratch build. You drop a JavaScript widget onto your page, and it handles the conversational UI: message bubbles, typing indicators, and streaming text rendering.
The authentication pattern is where ChatKit earns its keep. Your frontend never touches your OpenAI API key directly. Instead, your backend generates a short-lived client secret and hands it to the widget through a function typically called something like getAppAuthToken. The widget uses that ephemeral token to talk to OpenAI's servers, and the token expires quickly, which limits the damage if it ever leaks. This ephemeral-token pattern is the same principle behind OAuth access tokens: short life, narrow scope, low blast radius.
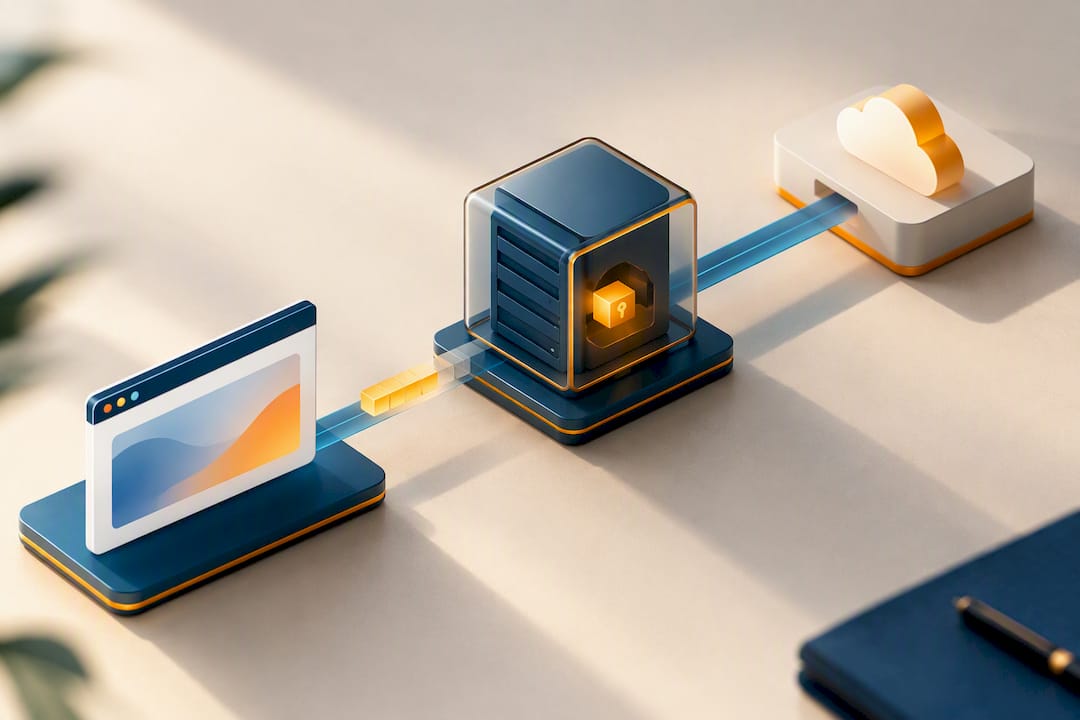
You have two deployment choices. The hosted route lets OpenAI manage the chat server infrastructure, which means less to maintain but less control over data residency and customization. The advanced, self-hosted ChatKit setup lets you run your own ChatKit server, exposing your own endpoints and streaming results through frameworks like FastAPI. Self-hosting matters most for teams with data residency requirements or those who want to inject custom business logic before a response reaches the user.
Here is where teams commonly get stuck:
| Pitfall | What Happens | Fix |
|---|---|---|
| Missing script in rendered HTML | Widget never appears because the page renders client-side after the script check runs | Confirm the ChatKit script tag exists in the server-rendered or hydrated HTML, not just the source template |
| Content Security Policy blocks | Browser console shows blocked requests; widget loads but never connects | Add OpenAI's ChatKit domains to your CSP connect-src and script-src directives |
| Incorrect token exchange | Widget shows an auth error or spins indefinitely | Verify your backend issues a fresh ephemeral token per session rather than reusing a static key |
| Token expiring mid-conversation | Chat drops silently after a few minutes of use | Implement token refresh logic before expiry, not just on initial load |
Full setup details, including the exact token exchange flow and SDK reference, live in OpenAI's ChatKit documentation.
What Does a Raw OpenAI API Integration Require?
Building directly on the OpenAI API gives you the most control, and it demands the most from your engineering team. This is the path for product teams that need a chat experience woven into their actual application logic, not sitting beside it.
- Put a server-side proxy between your frontend and OpenAI. Your API key lives only on the backend, never in browser JavaScript or a mobile app bundle. The proxy also enforces rate limiting per user or session, so one visitor cannot burn through your entire monthly token budget in an afternoon.
- Choose your streaming transport. Server-Sent Events or WebSocket connections let your backend push tokens to the browser as the model generates them, producing the word-by-word typing effect users expect from a modern chat interface. This token-by-token streaming pattern cuts perceived latency dramatically, even when total response time is unchanged.
- Build your retrieval-augmented generation (RAG) pipeline. Ingest your site content, chunk it into manageable passages, generate embeddings for each chunk, and store them in a vector database. When a user asks a question, your retriever pulls the most relevant chunks and feeds them to the model as context, so answers stay grounded in what your business actually publishes rather than the model's general training data.
- Design citation behavior into the prompt. Instruct the model to reference the specific page or section it drew from, and to say plainly when it does not have enough information rather than guessing.
- Set operational guardrails. Track token spend per conversation, cap message length, log errors without logging personal data, and build a small test suite of representative questions you rerun after every prompt change.
The official SDKs and CLI cover Node.js, TypeScript, and other environments, and OpenAI recommends the Agents SDK when your assistant needs to orchestrate multiple tools or steps rather than answer in a single pass. A single retrieval layer serving every channel, website, app, and internal tools alike, keeps answers consistent instead of drifting depending on where the question was asked, a point Intellowork's chatbot guide makes well.
Monitoring is not optional here. Without dashboards tracking latency, error rate, and refusal rate, you find out about a broken integration from an angry email, not a metric.
Are Hosted Chatbot Wrappers Worth It for Most Businesses?
For teams without dedicated engineering time, a hosted wrapper is usually the fastest way to get a working assistant live, and the installation itself often really is a two-line embed script. The harder work, as LaunchGPT's implementation guide points out, happens before that script ever gets pasted in: deciding what content the bot should and should not answer from.
A solid wrapper typically bundles:
- Automatic site crawling and content ingestion, so you are not manually feeding it every page.
- Built-in RAG, meaning it grounds answers in your actual content rather than general knowledge.
- Usage analytics showing what visitors ask and where the bot fails.
- Human handoff for questions it cannot answer confidently.
- Basic abuse protection against spam and prompt injection attempts.
Before you commit to one, run it through an evaluation checklist:
- Grounding quality — does it cite the source page, or does it confidently invent answers?
- Data export — can you pull your conversation logs and analytics out if you switch providers?
- PII handling — does it redact phone numbers, emails, and addresses from stored transcripts?
- Integrations — does it connect to your CRM or help desk, or does it live in isolation?
- Support SLA — what happens when the widget breaks at 2 a.m. on launch day?
Pro Tip: Before your wrapper goes live, manually exclude outdated pricing pages, discontinued product listings, and old blog posts from the crawl. An assistant that confidently quotes last year's prices is worse than no assistant at all.
Watch for three quick-start risks: a Content Security Policy that silently blocks the embed script, aggressive page caching that serves visitors a stale version of the widget, and content exclusions left too loose, which lets the bot hallucinate answers from pages you meant to keep out of scope.
Best Practices for Grounding, Privacy, and Cost Control
The technical build is only half the job. How you configure grounding, privacy, and placement determines whether the assistant builds trust or torches it.
- Require citations and honest refusals. Configure your RAG pipeline so the model cites the page it pulled from, and instruct it to say it does not know rather than guessing when retrieval comes up empty.
- Never expose your API key client-side. Route every request through a server proxy, use ChatKit's ephemeral token exchange, or issue short-lived credentials scoped to a single session.
- Redact personal data before it gets logged. Strip emails, phone numbers, and account details from stored transcripts, and keep only what you need for quality review.
- Document your data flow for privacy compliance. GDPR and CCPA both require you to know where user input goes, how long it is retained, and who can access it. This does not need to be complicated, but it does need to exist on paper.
- Place the widget where intent is highest. Placement research on converting chatbot deployments points to pricing pages, the bottom of documentation, and inside contact forms as the spots where visitors are most likely to engage rather than dismiss the widget.
- Control cost through model selection and rate limits. A smaller, faster model like GPT-4o-mini handles most support questions at a fraction of the token cost of a flagship model, and per-session rate limits stop a single bad actor from generating a runaway bill.
A production integration lives or dies on the retrieval layer, not the chat widget. Two sites can run the identical embed script and deliver completely different experiences depending on how carefully the underlying content was crawled, chunked, and triaged before launch, exactly why content triage matters so much before you ever write a single prompt.
How Do You Roll Out a ChatGPT Website Assistant?
A realistic launch runs in five stages, and skipping straight to "install the widget" is how most rollouts stall out at month two.
- Decide scope and pick your path. Choose between a wrapper, ChatKit, or the raw API based on team size, timeline, and how much custom control you actually need.
- Crawl and triage your content. Pull in every page, then strip out anything stale, superseded, or likely to produce a bad answer, and write explicit refusal rules for topics outside scope.
- Build the backend proxy and wire up the embed. Implement ephemeral token exchange or your server proxy, connect the streaming UI, and confirm the widget renders correctly across browsers.
- Test with real questions before launch. Run 30 to 50 realistic visitor questions through the assistant, confirm human handoff triggers correctly, and fix any grounding gaps you find.
- Monitor and iterate after launch. Track answer rate, citation rate, and assisted conversion weekly for the first month, then adjust content coverage based on what visitors actually ask.
Most wrapper deployments go live in days. ChatKit builds typically run one to three weeks depending on customization. Full raw API integrations with a proper RAG pipeline usually take four to eight weeks for a first production release.
What an Agency Adds to a ChatGPT Website Rollout
Building the technical pipeline is one job. Keeping it accurate, visible, and improving month over month is a different, ongoing job, and it is where most in-house teams lose momentum after the initial launch excitement fades.
The real work after launch is not the chatbot. It is the content triage that feeds it, the prompt tuning that keeps refusals honest, and the visibility work that gets your business surfaced in AI answers in the first place.
Digital Marketing All approaches chat deployment as one piece of a broader AI visibility strategy. It involves crawling and triaging site content for grounding, tuning prompts as products and pricing change, and layering in autosuggest and AI-recommendation optimization so your business shows up in the answers ChatGPT gives about your industry, not just the answers your own widget gives.
Build vs. Buy: A Practical Recommendation
If you run a small team without dedicated engineering bandwidth, start with a hosted wrapper or ChatKit. Both get you live in days rather than months, and both hand you grounding, analytics, and abuse protection out of the box. The cost of moving fast here is lower control, not lower quality, and for most businesses that trade is the right one.
If you are a product-engineering team that needs deep integrations, custom streaming behavior, or strict compliance controls over where user data lands, build on the raw API. That path costs more in engineering time, but it is the only one that gives you full ownership of the retrieval pipeline and the audit trail regulators will eventually ask for.
Whichever path you choose, track the same core metrics: answer rate, citation rate, honest refusal rate, and assisted conversion. A chatbot that answers confidently but rarely cites its source is a liability wearing a helpful mask. One that admits what it does not know, and points visitors to a human when it matters, earns the trust that actually drives conversions.
— Diane O'Brien
Getting Help With Implementation and AI Visibility
Digital Marketing All is the alternative to hiring and managing an in-house engineering team for a ChatGPT rollout: instead of juggling a wrapper vendor, a prompt tuner, and a visibility consultant separately, you get all three under one roof. Our AI Chatbot implementation work pairs with our Get Found In AI service, so your assistant is not just answering questions on your site, it is also part of a strategy to get your business surfaced when people ask ChatGPT about businesses like yours.
A typical engagement starts with a content audit to flag what is safe to ground the assistant on, moves through implementation and testing, and continues with ongoing monitoring and prompt tuning as your offerings change. If your website itself needs a rebuild to support a modern chat experience, our high-converting website design service handles that piece too. Visit our main services page to see the full lineup and get a plan built around your team's actual constraints.
Authoritative Docs and Guides
For implementation details straight from the source, bookmark the OpenAI API documentation, the ChatKit guide, and advanced ChatKit integrations. To understand how crawlers and bots interact with your site by default, review robots.txt, the standard opt-out mechanism every site owner should know.
Sources
FAQ
Can I Use ChatGPT on My Website?
Yes. You can embed ChatGPT through a hosted wrapper, OpenAI's ChatKit SDK, or a custom build on the raw OpenAI API. Most businesses start with a wrapper or ChatKit for speed, then move to a custom API integration only if they need deeper control.
Can You Use ChatGPT on a Web Browser?
Yes, ChatGPT runs natively in any web browser at chat.openai.com, and browser extensions like WebChatGPT add live web search to a personal session. That is different from embedding a site-specific assistant on your own website for visitors to use.
What Should You Not Tell ChatGPT?
Avoid entering sensitive personal data, passwords, financial account numbers, or confidential business information into any chatbot, including one embedded on a website. On the implementation side, never expose your OpenAI API key in frontend code; always route requests through a server-side proxy or ephemeral token exchange.
Can I Use GPT Online for Free?
ChatGPT offers a free tier for personal use directly through OpenAI's website. Embedding ChatGPT on your own site is a separate, paid arrangement, since it runs through the OpenAI API or a hosted wrapper service, both of which bill based on usage or a subscription fee. Current service pricing for related implementation and visibility work is listed on the provider's site.
Recommended
- Boost Your Business Visibility in ChatGPT: Master These 3 Query Types to Dominate AI Search
- Supercharge Your Business: Leverage ChatGPT and SEO for Explosive Growth in 2025
- Skyrocketing Your Business Website with ChatGPT and SEO Heading Tags
- Revolutionize Sales: Shopify ChatGPT Integration for Direct Buys | Act Before Holidays